What Is Pagination in API? 5 Simple Ways to Scale Fast
Imagine building a web application—a directory of community services that is rapidly outgrowing its database. When you first attempt to fetch all the listings for a single page, the app freezes and the server groans. It feels like trying to drink from a firehose! This is a classic scenario that illustrates the necessity of API pagination. Discover how this technique breaks down massive datasets into smaller, manageable sips instead of sending everything in one huge gulp.
API pagination is a fundamental technique designed to manage and deliver large datasets efficiently and in a user-friendly manner. Instead of sending all available data in a single, potentially massive response, pagination divides these large datasets into smaller, more manageable segments, often referred to as “pages” or “chunks.” These pages are then returned sequentially through a series of API requests. This method ensures that applications only retrieve and process a limited amount of data at any given time, making interactions smoother and more reliable.
The primary goal of implementing pagination is to prevent common issues like server overload and timeout errors. By limiting the amount of data transferred per request—typically ranging from 10 to 100 items per page, depending on the specific API’s design and the nature of the data—APIs can maintain stable performance. Modern APIs widely adopt pagination to significantly improve response times, as servers don’t have to compile and send an entire dataset at once. This also leads to a reduction in bandwidth consumption, which is beneficial for both the API provider and the client application, especially in environments with limited network resources. Ultimately, pagination enhances the user experience by delivering data incrementally, allowing applications to display initial results quickly and load more as needed, rather than forcing users to wait for a complete dataset to download.
Beyond the immediate benefits of speed and reduced network strain, pagination offers significant technical advantages. It helps reduce memory consumption on both the client and server sides. Client applications, such as a web browser or a mobile app, only need to process and store one page of results at a time. This prevents the application from consuming excessive memory, which could lead to crashes or sluggish performance, particularly on devices with limited resources. Similarly, the server only needs to fetch and prepare a single page of data from its database, rather than loading an entire dataset into memory, which can be crucial for maintaining the stability and scalability of the API infrastructure.
A key piece of advice for developers starting with APIs is to never underestimate the importance of pagination. It’s often an afterthought, but without it, even the simplest app trying to display more than a handful of items will grind to a halt. Countless ‘slow loading’ issues can be traced back to a missing or poorly implemented pagination strategy.
How API Pagination Works
How Does Pagination Work in an API?
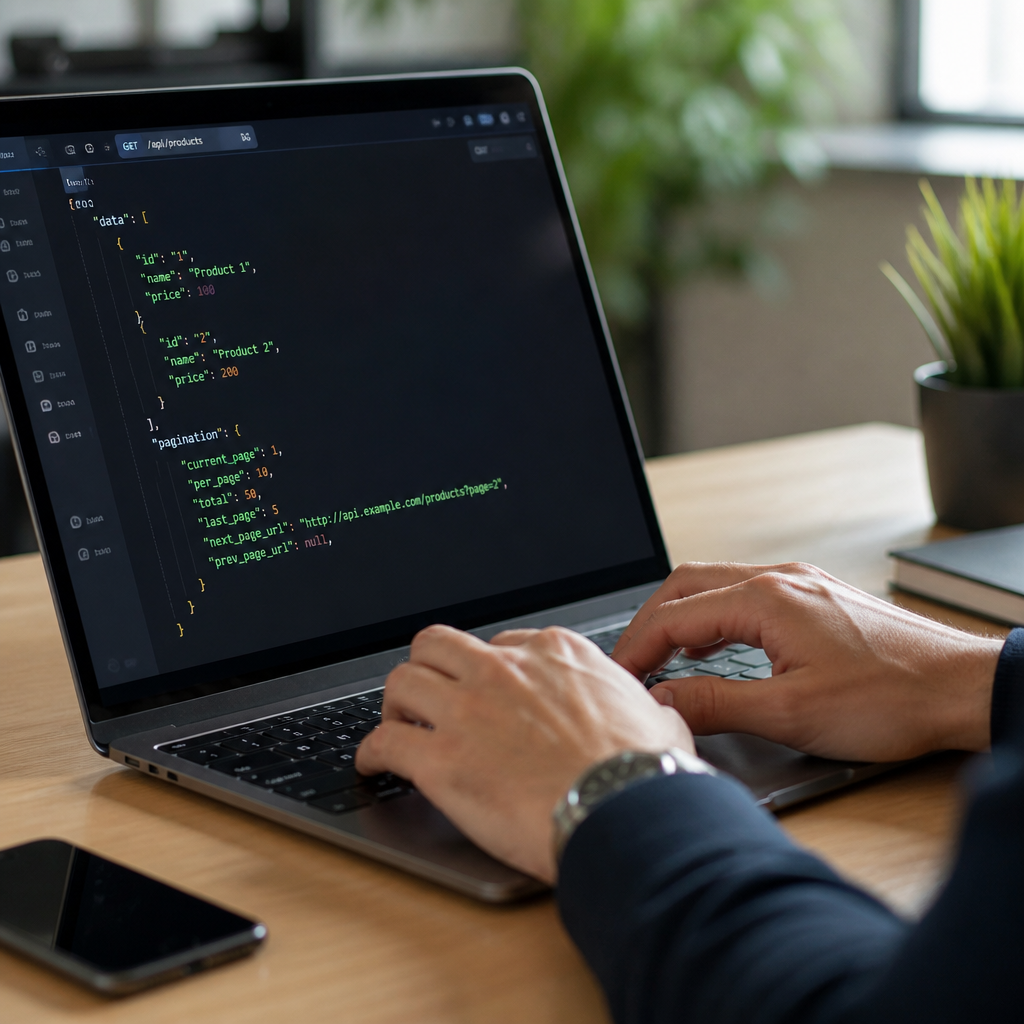
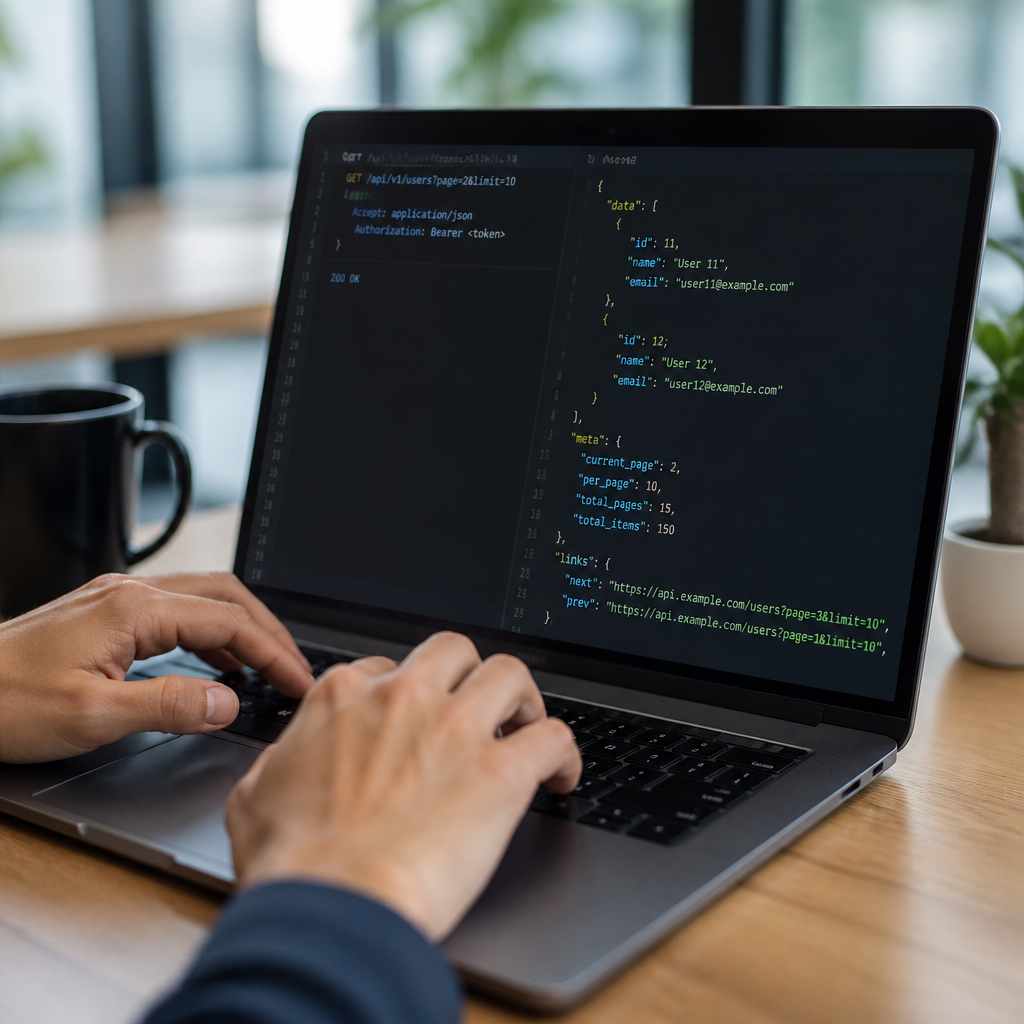
API pagination operates through a well-defined request-response cycle, where the client (like your web browser or phone app) and the server (where the data lives) collaborate to retrieve specific subsets of a larger dataset. This process begins with the client initiating a request, specifying which particular segment of data it wishes to retrieve. This specification is typically done using special parameters included in the request URL. In response, the server processes this request, queries its database to fetch the requested page, and then returns that specific page of data. Crucially, the server’s response also includes valuable “metadata”—data about the data—which provides information about the overall dataset and navigation links, empowering the client to seamlessly request subsequent pages.
The typical workflow for API pagination involves several distinct steps:
- Initial Request: The client sends an initial request to the API endpoint, embedding specific pagination parameters. These parameters inform the server about the desired page number, the number of items per page, or a specific starting point for the data.
- Server-Side Query: Upon receiving this request, the server translates these pagination parameters into appropriate database queries. For many traditional pagination methods, this involves using clauses like
LIMITandOFFSETin SQL databases or employing cursor values for more advanced pagination types. - Response Construction: After the database query is executed, the server constructs a response that contains the requested page of data. Alongside the actual data, the response includes essential metadata. Common fields found in pagination metadata often include
total_count,page_size,current_page,total_pages,next_page_url, andprevious_page_url. - Client-Side Processing: The client receives this response and utilizes the provided metadata to determine its next actions. If the user wishes to view more data, the client can construct a new request using the
next_page_urlor by incrementing thecurrent_pageparameter.
Servers often implement safeguards by setting default and maximum page sizes. For example, the GitHub API, a widely used platform, defaults to returning 30 items per page but allows clients to request up to a maximum of 100 items per page. These limits are crucial for preventing abuse, ensuring fair resource allocation, and maintaining the stability of the API for all users.
Types of Pagination in API
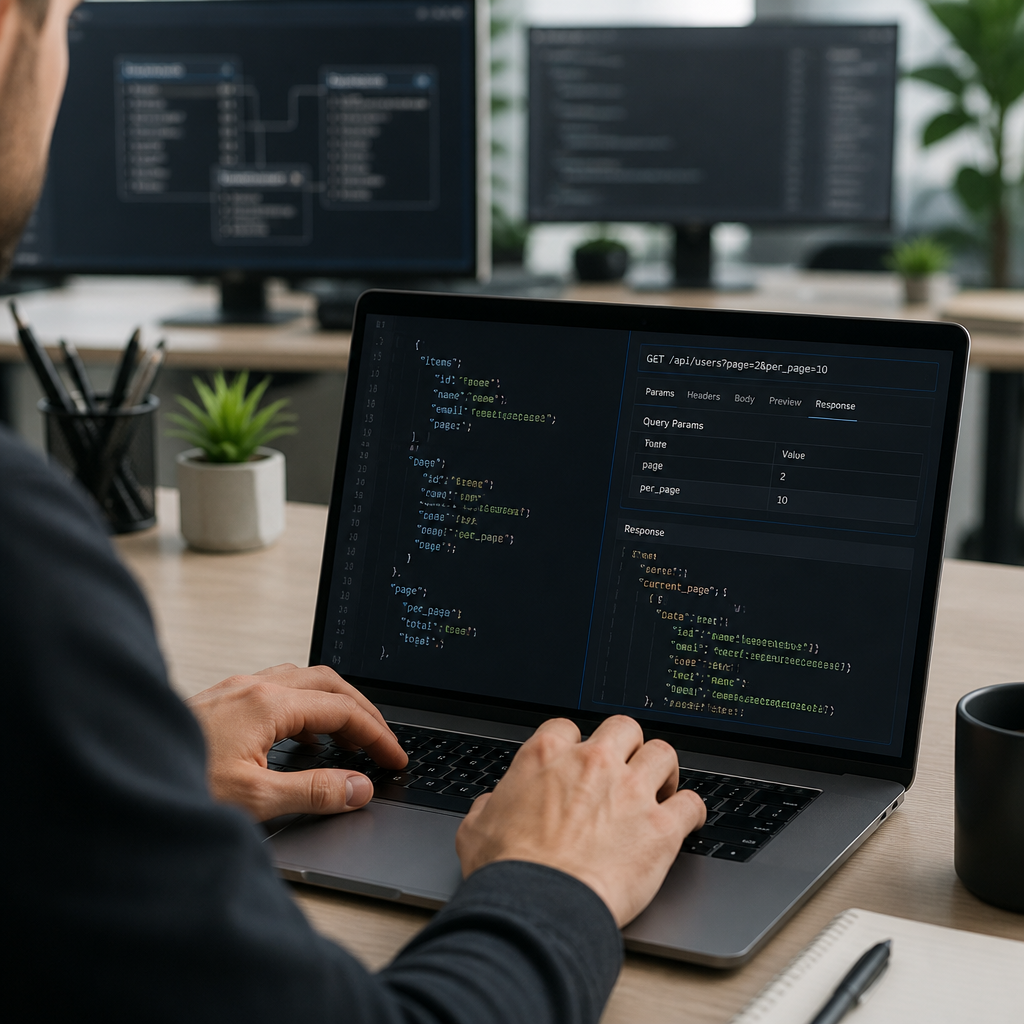
The landscape of API pagination offers several strategies, each with its own strengths and ideal use cases. The primary types are offset-based, which relies on page numbers or limit/offset parameters, and cursor-based, also known as keyset pagination. Understanding these different types is crucial for designing an API that is both efficient and user-friendly.
Offset-based pagination is perhaps the most intuitive and commonly understood method, largely because it mirrors the traditional page numbering found in books or web search results. While this method is straightforward, it can become inefficient for very large datasets, with performance degrading as the requested page number increases.
In contrast, cursor-based pagination offers a more robust and performant solution, especially for APIs dealing with large or frequently changing datasets. Instead of relying on page numbers, it uses an encoded pointer, or “cursor,” which references a specific record in the dataset. A significant advantage of cursor-based pagination is its consistency; it provides stable results even when data is added or deleted between requests.
Another notable approach is Link header pagination, adopted by prominent APIs like GitHub. This method returns navigation URLs within the HTTP Link headers, keeping the response body clean and containing only the requested data.
| Feature | Offset-Based Pagination | Cursor-Based Pagination |
|---|---|---|
| Mechanism |
Uses LIMIT and OFFSET to skip records.
|
Uses a “cursor” (pointer) to a specific record. |
| Performance | Degrades with deep pages (O(n) complexity). | Consistent and fast, even for deep pages (O(1) complexity). |
| Data Consistency | Prone to skipped/duplicate items in dynamic datasets. | Highly consistent; handles new data without issue. |
| Use Case | Best for smaller datasets or when random page access is needed. | Ideal for large, real-time, or frequently updated datasets. |
| Navigation | Allows jumping to any page number. | Typically sequential (next/previous page only). |
Choosing the right pagination type is a strategic decision that impacts an API’s performance, reliability, and overall user experience. For APIs serving real-time data or large datasets, cursor-based pagination is the gold standard because it maintains consistency even when records are added or deleted between requests.
Offset Pagination in API
Offset pagination, often referred to as limit-offset or page-number pagination, is a widely used method for dividing large datasets. This technique relies on two primary parameters: offset and limit. The offset parameter specifies the number of records to skip, while the limit parameter dictates the maximum number of records to return. These are often expressed as page and size in API requests.
The calculation for the offset value is offset = (page_number - 1) × page_size. In terms of database implementation, this typically leverages SQL’s LIMIT and OFFSET clauses, such as SELECT * FROM products ORDER BY id LIMIT 10 OFFSET 20.
Despite its simplicity, offset pagination has drawbacks. A significant performance issue arises on large datasets because databases must scan and skip all offset rows before returning results. This scanning overhead increases linearly with the offset value, leading to performance degradation as users navigate deeper.
Another critical problem is data consistency. _If new records are added or existing ones are removed between paginated requests, the offset can become misaligned, leading to duplicate or missed items._ This can be a major problem for applications that require high data integrity.
However, offset pagination’s primary benefit is the ability to allow random access to any page. This feature is highly valued in applications like administrative dashboards or search results where users might want to navigate directly to a specific section of the data.
While offset-based pagination is the easiest to implement and understand, it’s fundamentally flawed for production systems with active datasets. I’ve seen e-commerce APIs skip products during Black Friday sales because new items were added between page requests. For any dataset that changes frequently, cursor-based pagination is non-negotiable.
— Kin Lane, API Evangelist
Cursor-Based Pagination in API
Cursor-based pagination, or keyset pagination, represents a more advanced and performant approach. It uses an encoded pointer, known as a “cursor,” to reference a specific record’s position, allowing the API to fetch the next set of results relative to that cursor.
Technically, a cursor is typically a base64-encoded string containing the unique identifier (ID) and the sort key of the last item from the previous page. The server decodes this cursor to identify the exact record from which to start the next query. The implementation in databases typically involves using WHERE clauses instead of OFFSET. For instance, a SQL query might look like SELECT * FROM posts WHERE (created_at, id) > ('2024-01-15', 100) ORDER BY created_at, id LIMIT 20.
The performance advantage of cursor-based pagination is its most compelling feature. It maintains consistent, O(1) performance even with millions of records because it relies on indexed columns for direct lookups. Furthermore, it offers superior data consistency, preventing the common issues of duplicate or skipped items that can occur with offset pagination.
Despite its advantages, cursor pagination has limitations. It generally does not support random page access, and it usually does not provide a total count of items or pages. Clients must rely on hasNextPage or hasPreviousPage indicators to know if more data is available. A notable implementation example is found in GraphQL’s Relay specification, which has been widely adopted by major platforms like Facebook and GitHub. For best practices, cursors should always be opaque, meaning they are encoded strings that clients cannot easily decipher or manipulate.
Implementing and Optimizing API Pagination
How Can You Implement Pagination in an API?
Implementing API pagination involves choosing a strategy, designing request parameters and response structures, writing robust database query logic, including comprehensive metadata, and documenting the entire scheme.
The first step is to choose the appropriate pagination type. For smaller datasets or when users need to jump to any page, offset pagination might be suitable. For large, dynamic datasets, such as social media feeds, cursor-based pagination is preferred for its superior performance and data consistency.
For offset pagination, the implementation involves accepting page and limit as query parameters. It’s crucial to validate these parameters, setting reasonable default values and enforcing a maximum limit. The server then calculates the offset and uses it in the database query.
Implementing cursor pagination requires accepting cursor and limit parameters. The server decodes the cursor to extract the unique identifier and sort key of the last record. The database query then uses a WHERE clause based on these values. After fetching the results, the server encodes the details of the last record in the current page to generate the next_cursor for the client.
The response structure is vital. It should contain the data along with clear and consistent metadata, such as current_page and total_pages for offset, or next_cursor and hasNextPage for cursor.
Regardless of the pagination type, creating appropriate indexes on the columns used for sorting and filtering in pagination queries is paramount for performance. Robust error handling is also crucial. API implementations should validate pagination parameters rigorously, returning a 400 Bad Request status code for invalid inputs.
Pagination in API Performance
API pagination performance is critical for designing scalable and responsive APIs. Key metrics include response time, database query execution time, and memory usage.
Offset pagination exhibits a linear degradation in performance as the page number increases. This is due to the database’s need to scan and skip all preceding rows. In stark contrast, cursor-based pagination is designed to maintain consistent performance, often achieving sub-50ms response times regardless of depth, provided the database is properly indexed.
The database impact of large OFFSET values is substantial, consuming significant CPU and I/O resources. _On very large tables, a SELECT COUNT(*) query can become an extremely expensive operation, potentially locking tables or causing significant database strain._
To optimize performance, developers can employ techniques like caching frequently accessed pages and using covering indexes. A covering index includes all columns needed in a query, eliminating the need for additional table lookups. Network performance is also influenced by the chosen page size; the optimal size is a trade-off between fewer requests (larger size) and faster initial loads (smaller size).
Monitoring P95 and P99 response times across different page numbers can reveal performance degradation patterns, signaling when a switch from offset to cursor pagination should be considered.
The performance difference between offset and cursor pagination becomes dramatic at scale. In a production system I optimized, switching from offset to cursor pagination reduced P99 latency from 2.3 seconds to 45 milliseconds for deep pagination on a 50-million-row table. The database went from 80% CPU utilization to 15%.
— Baron Schwartz, Database Performance Expert
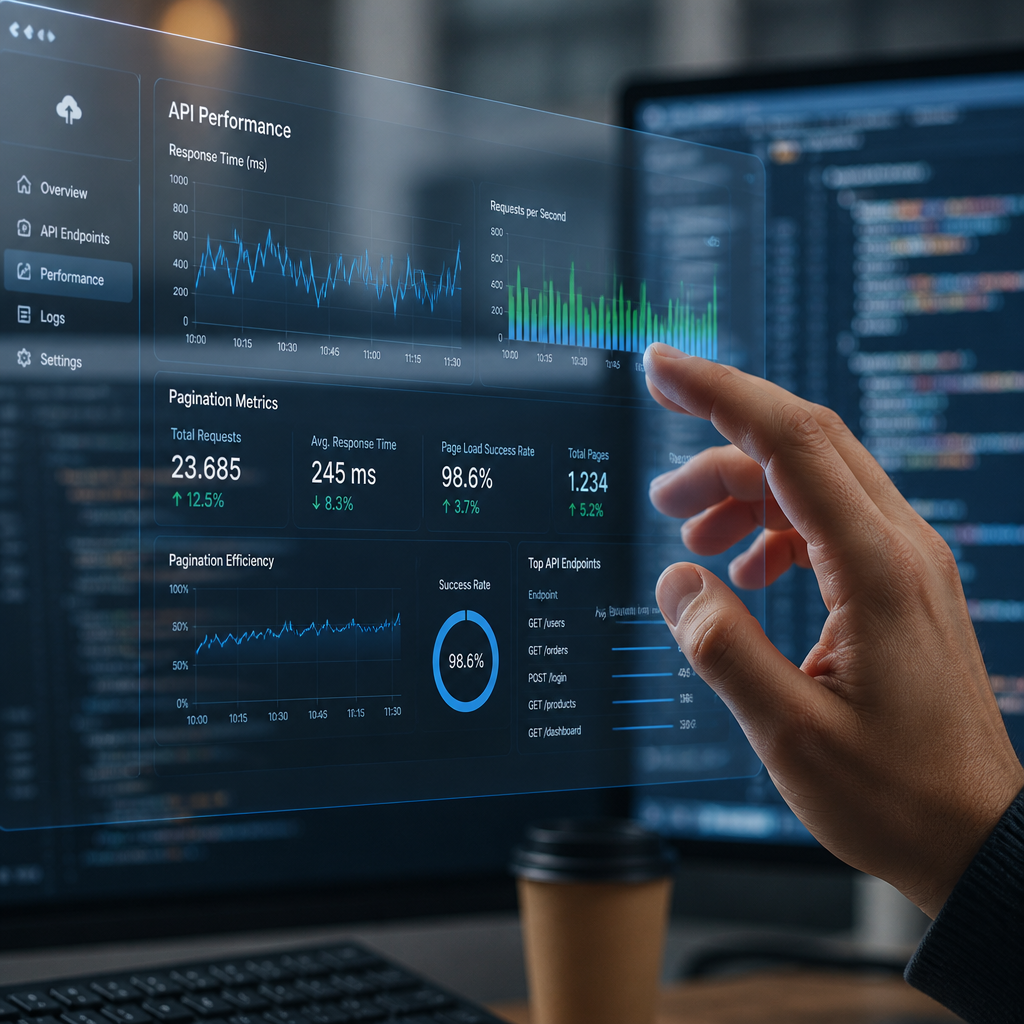
Pagination in API Best Practices
Implementing pagination effectively involves adhering to best practices that ensure an API is robust, performant, secure, and user-friendly.
- Set Default and Max Limits: A fundamental best practice is to set reasonable default page sizes (e.g., 20-50) and enforce maximum limits (e.g., 100-200) to prevent resource exhaustion.
- Provide Comprehensive Metadata: Always include metadata in responses, such as
total_pagesfor offset orhasNextPagefor cursor, to empower client applications. - Ensure Stable Sorting: Use a unique identifier (like an
id) as a tiebreaker in the sort order (e.g., sort bycreated_atthenid) to prevent items from being skipped or duplicated. - Use HATEOAS Links: For RESTful APIs, include full URLs for
next,previous,first, andlastpages directly within the API response to make the API more self-descriptive and reduce client-side errors. - Document Thoroughly: Clearly document the pagination type, parameters, default/max values, and the expected metadata structure.
- Validate and Sanitize Inputs: All pagination parameters must be validated to prevent security vulnerabilities like SQL injection and resource abuse.
- Make Cursors Opaque: For cursor pagination, encode cursors so clients cannot manipulate their internal structure.
- Use Appropriate HTTP Status Codes: Return
200 OKfor successful requests (even with an empty data array) and400 Bad Requestfor invalid parameters. Avoid using404 Not Foundfor out-of-range pages.
FAQ
Q1: What is the main purpose of API pagination?
A1: The main purpose of API pagination is to divide large datasets into smaller, manageable chunks (pages) that are returned sequentially through API requests. This prevents server overload, reduces bandwidth consumption, improves response times, and enhances user experience by delivering data incrementally, rather than attempting to send all data in a single, potentially overwhelming response.
Q2: What are the primary types of API pagination, and how do they differ fundamentally?
A2: The primary types are offset-based pagination and cursor-based pagination. Offset-based pagination uses page numbers and a limit/offset to skip a certain number of records and retrieve the next set. It’s intuitive but can be inefficient for large datasets. Cursor-based pagination uses an encoded pointer (cursor) to a specific record, fetching results relative to that point. It offers better performance and data consistency for large, dynamic datasets but does not support random page access.
Q3: Why does offset pagination often suffer from performance degradation on large datasets?
A3: Offset pagination degrades in performance on large datasets because the database must scan and skip all the records up to the specified offset before it can retrieve the desired page. For example, to get page 1000 with 10 items per page, the database has to scan 9,990 records just to find the starting point of the 10 records for page 1000. This process consumes significant CPU and I/O resources, leading to slower response times as the offset increases.
Q4: What are the key advantages of cursor-based pagination over offset pagination?
A4: Cursor-based pagination offers several key advantages: it maintains consistent performance regardless of dataset size (O(1) complexity when indexed) because it uses direct index lookups; it provides stable data consistency, preventing duplicate or skipped items even when data changes between requests; and it reduces database load by avoiding the need to scan and skip rows.
Q5: What are some essential best practices for implementing API pagination?
A5: Essential best practices include setting reasonable default page sizes (20-50 items) and enforcing maximum limits (100-200) to prevent resource exhaustion. Always include comprehensive pagination metadata in responses (e.g., current page, total items, next/previous cursors). Use consistent sorting with stable sort keys (including unique IDs as tiebreakers). Document the pagination scheme clearly, validate and sanitize all pagination parameters for security, and return appropriate HTTP status codes (200 OK for success, 400 Bad Request for invalid parameters).

Hi, I’m Anna Smith, the founder of API Dev Note.
I’m an API specialist with experience working with APIs, integrations, and web development. Through hands-on projects, I’ve learned that understanding how APIs work in real-world environments is just as important as reading the documentation.