What Is API Rate Limiting? 7 Smart Ways to Stay Secure
API rate limiting acts as a traffic controller for a website’s “front door” (its API), ensuring no single user or group floods the entrance and prevents others from getting in. In essence, it sets a clear cap on how many requests a user or client can make within a certain amount of time. This mechanism is crucial for keeping online services stable, secure, and fair for everyone. Without it, a single user or a bad actor could easily overwhelm a server, leading to frustrating slowdowns or even total outages. By acting as a digital traffic controller, this process helps make sure resources are shared fairly and that the underlying systems stay up and running smoothly. It is a non-negotiable part of building robust and reliable digital experiences, from large social media platforms to essential financial services.
Core Concepts of API Rate Limiting
How Does API Rate Limiting Work?
API rate limiting acts as a protective shield for backend services. It carefully controls the number of incoming requests to stop the system from getting overloaded and to make sure everyone gets fair access. Basically, it sets a maximum number of requests a client can send to an API in a specific time frame—for example, 100 requests per minute. The process usually begins when an API gateway or middleware first receives an incoming request. This step is critical because it lets the system check and manage requests before they reach the main application logic.
Once a request is intercepted, the system identifies the client. This can be done through unique API keys, the client’s IP address, or OAuth tokens that prove a user’s identity. Identifying the client is key to ensuring that limits are applied correctly to each user. After identifying the client, the system checks their recent request history, which is typically stored in high-speed, in-memory data stores like Redis or Memcached. These technologies are chosen for their ability to read and write information in milliseconds, which is essential for making real-time decisions without slowing down the API’s response.
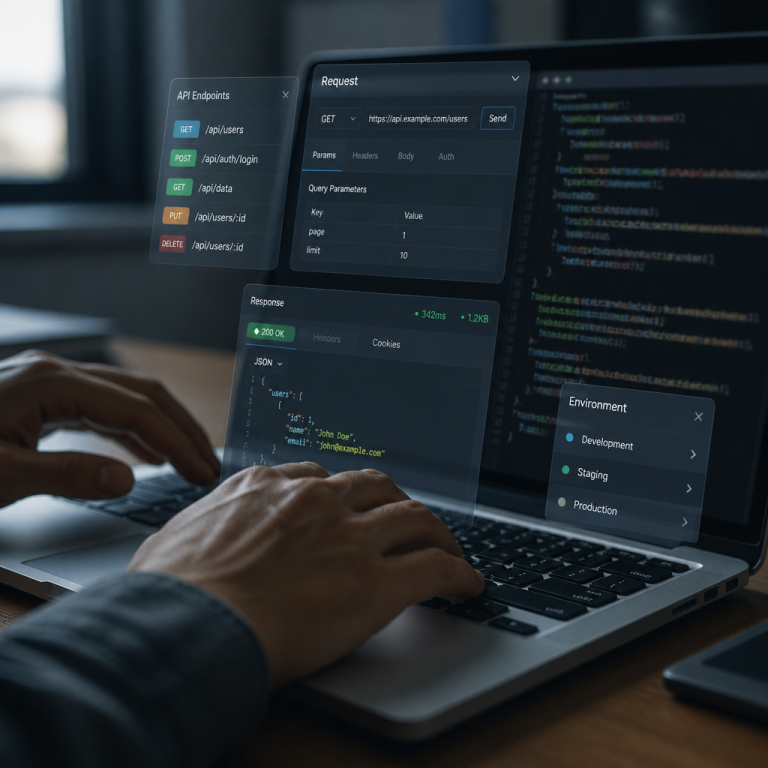
Based on predefined rules and the client’s request count, the system decides whether to allow the request to proceed or to reject it. If the limit has been reached, the API typically returns an HTTP 429 “Too Many Requests” response. Along with the 429 status code, the API often includes helpful information in the response headers.
X-RateLimit-Limit: The maximum number of requests allowed in the time window.X-RateLimit-Remaining: The number of requests remaining in the current window.X-RateLimit-Reset: The time when the limit will reset.Retry-After: A suggestion for how long the client should wait before sending another request.
This layered approach means organizations can fine-tune their strategies to perfectly match their needs, helping to keep everything safe and running at top speed.
API Rate Limiting Algorithms Explained
Rate limiting algorithms are the core logic that determines how request quotas are measured, refilled, and enforced over time. Understanding these algorithms is a major step toward implementing an effective strategy.
The Token Bucket is one of the most common algorithms. Imagine a bucket that can hold a certain number of tokens, and new tokens are added at a steady rate. Every time a client makes a request, they use one token. If tokens are available, the request is processed; if the bucket is empty, the request is rejected. Its ability to handle bursts of traffic makes it ideal for real-world API usage patterns, where traffic is not always smooth.
In contrast, the Leaky Bucket algorithm smooths traffic by processing requests at a constant rate. Requests are added to a queue and processed in a first-in-first-out (FIFO) manner. If the queue becomes full, new requests are rejected. This algorithm is excellent for protecting services that require a steady inflow of traffic, as it prevents sudden floods from overwhelming them.
The Fixed Window algorithm is the simplest to implement. It divides time into fixed segments, or windows, and counts the requests within each window. If the count exceeds the limit, further requests are rejected until the window resets. _While simple, this method has a significant drawback known as the “boundary issue,” where a client could send a burst of requests straddling two windows, effectively doubling their allowance for a short period._
To address the flaws of the fixed window, the Sliding Window Log algorithm offers greater accuracy. It stores a timestamp for each request from a client. When a new request arrives, it removes all timestamps older than the current time window and then counts the remaining timestamps. If the count is over the limit, the request is rejected. This method provides precise rate limiting but can be memory-intensive since it stores individual timestamps for every request.
A more memory-efficient hybrid is the Sliding Window Counter algorithm. It combines the fixed window and sliding window log approaches. It calculates an approximate request count in the current window by considering the count from the previous window and the overlap between the two. This method provides a good balance between accuracy and memory usage.
| Algorithm | Memory Usage | Burst Allowance | Traffic Smoothing | Boundary Issues |
|---|---|---|---|---|
| Token Bucket | Low (O(1)) | Yes | Moderate | No |
| Leaky Bucket | High (O(n)) | No | High | No |
| Fixed Window | Low (O(1)) | No | Low | Yes |
| Sliding Window Log | High (O(n)) | No | High | No |
| Sliding Window Counter | Low (O(1)) | Limited | Moderate | No |
What Is the Difference Between API Throttling vs. Rate Limiting?
Although “API throttling” and “rate limiting” are often used interchangeably, they refer to distinct but related traffic management strategies. The main difference is how they handle requests once a predefined limit is approached or exceeded. Rate limiting is a more binary, all-or-nothing control, whereas throttling is a more graceful, gradual approach.
Rate limiting operates on a strict allow-or-deny basis. When a client exceeds the permitted number of requests in a given period, the rate limiter immediately rejects subsequent requests, typically with an HTTP 429 “Too Many Requests” response. The primary objective of rate limiting is to enforce hard boundaries to protect the API from being overloaded, whether by malicious attacks or accidental over-usage. It is a clear line: cross it, and access is denied.
Throttling, on the other hand, is a more nuanced technique. Instead of rejecting requests outright, throttling aims to slow down the request processing rate as limits are approached. This might involve introducing delays, queuing requests for later processing, or prioritizing certain requests over others. The goal is to maintain service availability and stability by gracefully degrading performance rather than abruptly cutting off access. Throttling is highly effective in situations where maintaining some level of service, even if slower, is preferable to a complete shutdown during traffic spikes.
Benefits, Use Cases, and Best Practices
API Rate Limiting Benefits and Use Cases
API rate limiting offers numerous advantages that are essential for maintaining the stability, security, and profitability of any API-dependent service. These benefits range from infrastructure protection to enabling sophisticated business models. At its heart, this control is a critical tool for protecting your infrastructure. By controlling the influx of requests, it shields servers and databases from being overwhelmed by intentional Distributed Denial of Service (DDoS) attacks or unintentional traffic spikes.
Beyond protection, the process is a powerful tool for cost control. For companies using cloud services, unchecked API usage can lead to significant bills for compute power and bandwidth. By setting limits, businesses can effectively cap infrastructure spending. Another key benefit is fair resource allocation. In a multi-tenant environment, it is crucial to prevent a single user or application from monopolizing API capacity. This ensures all users receive a consistent quality of service. Furthermore, this mechanism can be a cornerstone of monetization. It allows API providers to create tiered service levels (e.g., free, basic, premium), each with distinct rate limits.
The use cases for this technology are diverse, spanning multiple industries and architectural patterns. For public APIs, like those from Twitter, GitHub, and Google Maps, rate limiting is nearly universal. In microservices architectures, internal request limitation is crucial for preventing cascading failures. If one service experiences a surge in requests, it could overwhelm its dependent services. Rate limiting acts as a circuit breaker, improving the resilience of the entire distributed system. Finally, it is a vital security measure for preventing brute-force attacks on endpoints like login pages.
As Kin Lane, the “API Evangelist,” emphasizes, rate limiting isn’t just a technical setting; it’s a product design decision that deeply impacts how developers interact with a platform.
API Rate Limiting Best Practices
Implementing rate limiting effectively requires a strategic plan that balances user experience, system resilience, and business objectives.
- Establish Tiered Limits: Offer different rate limits based on factors like authentication status or subscription level (e.g., free vs. premium). It is absolutely crucial to clearly explain these different levels in your documentation so developers understand what access they have.
- Communicate Clearly: When a client hits a limit, the API should return a clear HTTP 429 “Too Many Requests” error. Crucially, the response should include informative headers like
X-RateLimit-Limit,X-RateLimit-Remaining,X-RateLimit-Reset, andRetry-After. - Use Granular Limiting: Apply different rate limits to different API endpoints based on their computational cost. Resource-intensive operations, like complex searches, should have stricter limits than simple, lightweight queries.
- Limit Across Multiple Dimensions: Apply limits per API key, per IP address, and per user account simultaneously. A multi-dimensional approach makes it much more difficult for malicious actors to circumvent controls.
- Design for Graceful Degradation: Client applications should anticipate and handle rate limit errors gracefully. This includes implementing strategies like exponential backoff, respecting the
Retry-Afterheader, and caching data to reduce API calls. - Monitor and Alert: Continuously track metrics such as rejected request counts, identify top consumers, and set up alerts for anomalous activity. This data can signal potential attacks or indicate that existing limits need adjustment.
- Provide an Allowlisting Mechanism: Have a formal process for trusted partners or internal services to request higher limits or exemptions from standard policies.
Marsh Gardiner, an expert in API Management Strategy at Google Cloud, advises against setting initial rate limits too low. _He suggests starting with generous limits based on your system’s capacity and only tightening them if data shows misuse or resource problems._
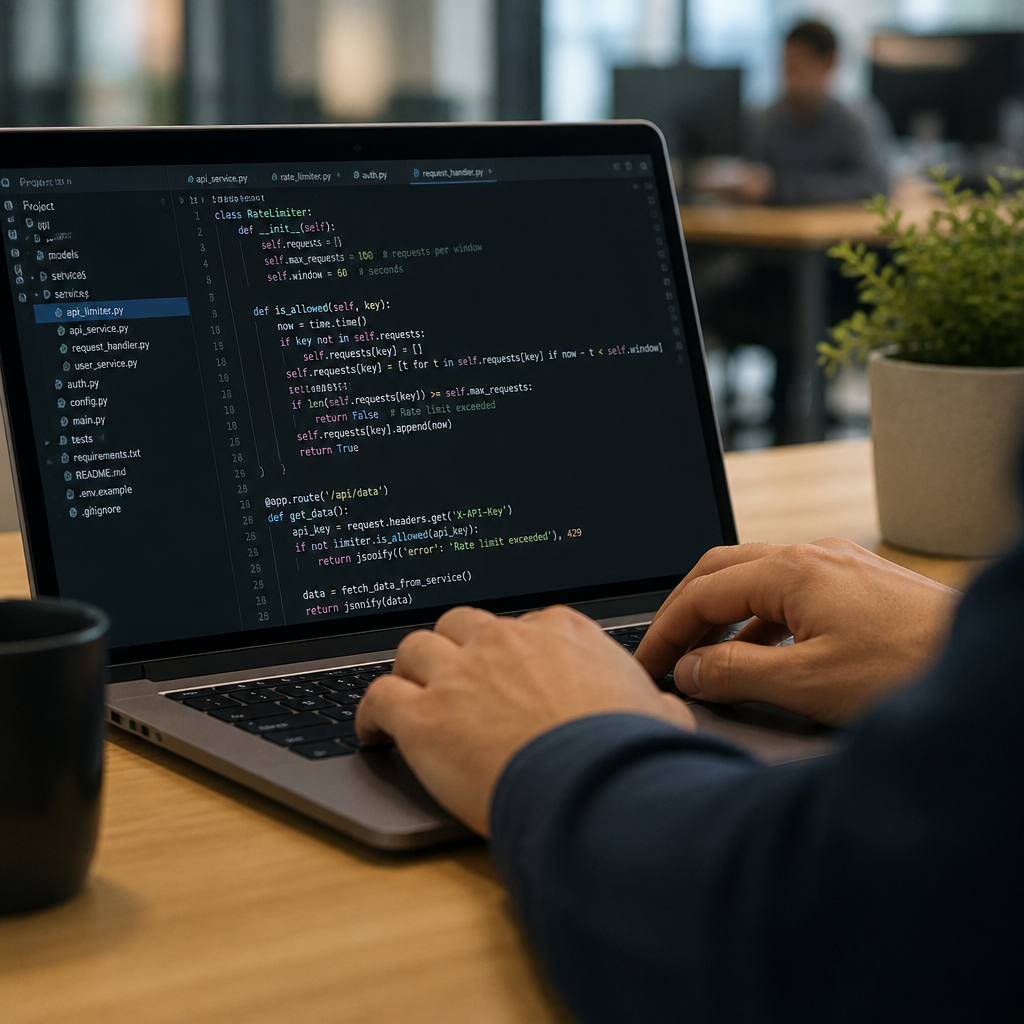
API Rate Limiting in Architecture and Tooling
API Rate Limiting vs. API Gateway
Understanding the relationship between rate limiting and an API gateway is fundamental to designing robust and scalable API architectures. An API gateway is the single entry point for all API requests, acting as a reverse proxy that sits in front of backend services. Its primary role is to handle cross-cutting concerns such as request routing, authentication, monitoring, and, crucially, rate limiting. In this context, rate limiting is a specific feature or capability commonly provided by an API gateway, not an entity separate from it.
While this control is a common feature implemented within API gateways, it can also be configured at other layers of the stack, such as directly in application code, at the load balancer level, or as standalone middleware. However, gateways offer a comprehensive suite of management features beyond just request limitation, including:
- Request routing and load balancing
- Authentication and authorization
- Request/response transformation
- Caching
- Logging and analytics
- SSL termination
- API versioning
Implementing this function within an API gateway offers several advantages. This central approach helps ensure that the rules are applied consistently across all microservices or backend applications. It simplifies management by providing a single point of configuration and reduces the need for redundant code in each service. Conversely, a decentralized approach (implementing in the application code) offers more granular control but can lead to inconsistent policies and increased development overhead. Popular gateway solutions like AWS API Gateway, Kong, and Apigee all come with robust, built-in rate limiting features.
_While API gateways offer big operational benefits, they do add a small amount of network delay, usually between 1-10 milliseconds, because requests have to go through an extra step._ However, this minor latency is often a worthwhile trade-off for the centralized control, security, and added performance features like caching that a gateway provides.
—
Conclusion:
API rate limiting is an essential component of modern web architecture, serving as a critical defense for service stability, security, and fair resource allocation. By intelligently managing the flow of requests, it shields backend systems from being overloaded, controls operational costs, and enables flexible monetization strategies. Whether implemented through sophisticated algorithms like the token bucket or managed centrally via an API gateway, its core purpose remains the same: to ensure that APIs remain performant and available for all legitimate users while preventing potential abuse. Unlock the full potential of your services by adopting best practices, from clear communication of limits to graceful error handling, which further enhances the effectiveness of these controls and fosters a resilient digital ecosystem.
FAQ
Q1: What is the primary purpose of API rate limiting?
A1: The primary purpose is to control the number of requests a client can make to an API within a specified time. This protects backend services from being overwhelmed, ensures fair resource allocation among users, and helps prevent malicious activities like DDoS attacks.
Q2: How do API rate limiting algorithms like Token Bucket and Leaky Bucket differ?
A2: The Token Bucket algorithm allows for traffic bursts by replenishing tokens at a constant rate, which requests consume. The Leaky Bucket algorithm smooths out traffic by processing requests at a constant rate from a queue, which does not allow for bursts.
Q3: What HTTP status code is typically returned when an API rate limit is exceeded?
A3: When an API rate limit is exceeded, the server typically returns an HTTP 429 “Too Many Requests” status code. This response often includes headers like Retry-After to inform the client when they can try again.
Q4: What are some key benefits of implementing API rate limiting?
A4: Key benefits include infrastructure protection from overload and attacks, cost control by limiting resource usage, fair resource sharing among all users, and enabling monetization through tiered service levels.
Q5: Is API rate limiting the same as an API gateway?
A5: No, but rate limiting is a common and critical feature provided by an API gateway. An API gateway is a broader system that acts as a single entry point for API requests, handling many tasks like routing, authentication, and monitoring in addition to rate limiting.

Hi, I’m Anna Smith, the founder of API Dev Note.
I’m an API specialist with experience working with APIs, integrations, and web development. Through hands-on projects, I’ve learned that understanding how APIs work in real-world environments is just as important as reading the documentation.